

See how the cluster is doing
Every cluster opens on its Overview. Four tiles say how many nodes are ready, how many pods are running, how many workloads are healthy, and how many warnings came in the last hour. Each tile links to its list, filtered to what’s wrong when something is.Below them, CPU and memory show what’s in use next to what’s requested, limited and allocatable, with a line of recent usage. Needs attention lists the pods and workloads in trouble, and Recent warnings the events that explain them.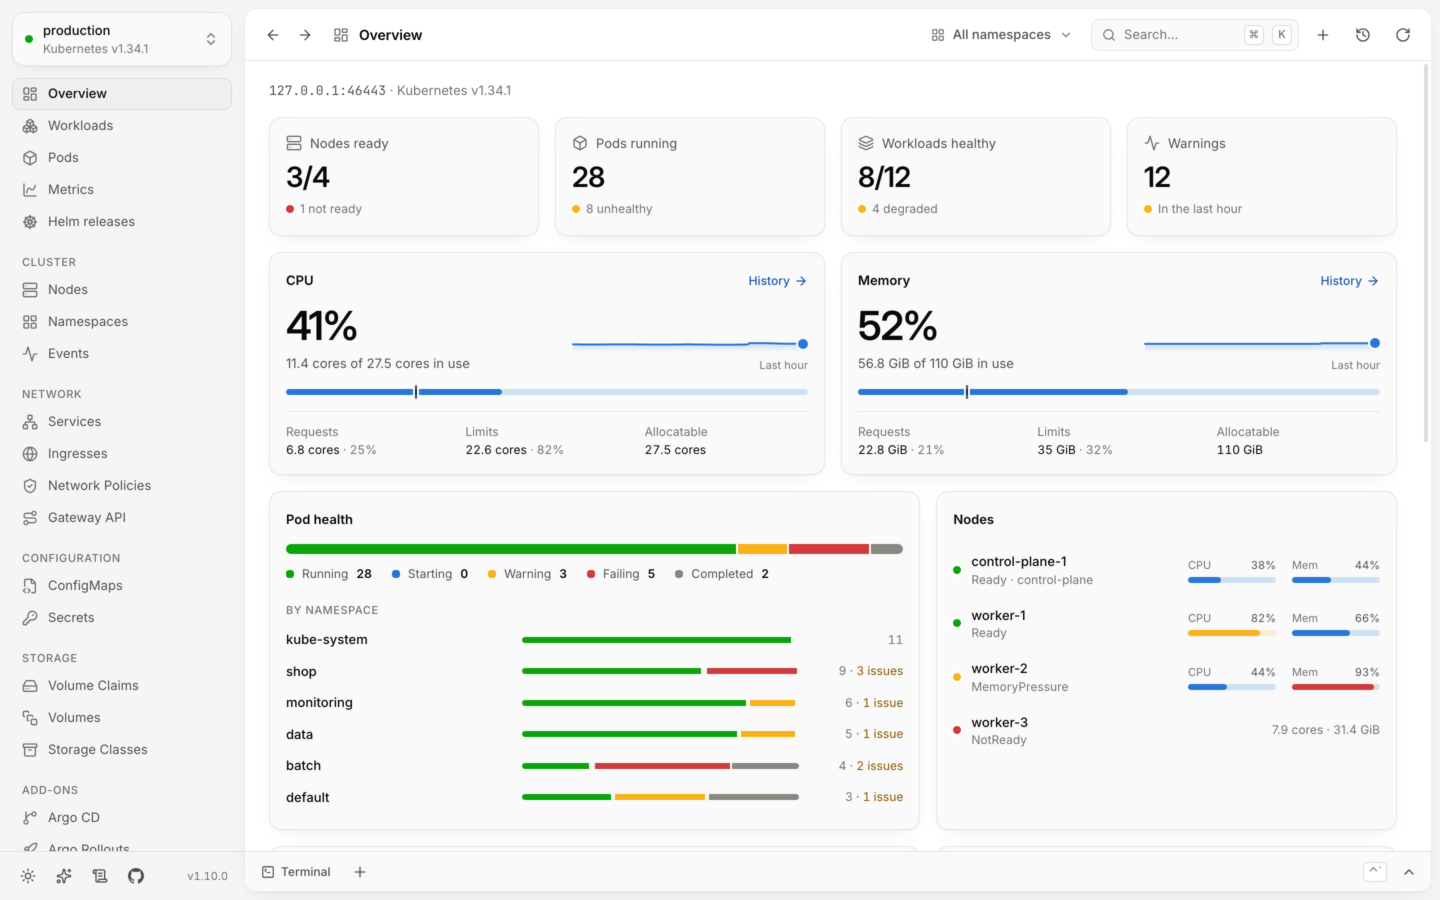


 The namespace menu at the top scopes every list. It starts in your kubeconfig context’s namespace, and remembers your choice per cluster. More about the overview.If your team’s Lumovi shows a fleet of clusters, its first page sums every cluster up the same way, on a card each, the ones that need attention first.
Find what's failing
Open Workloads (G then W). Every Deployment, StatefulSet, DaemonSet and CronJob is in one list, with the Jobs and pods that nothing else runs, each with its status, ready pods and the CPU and memory its pods use. Whatever is failing sorts to the top, whatever its kind.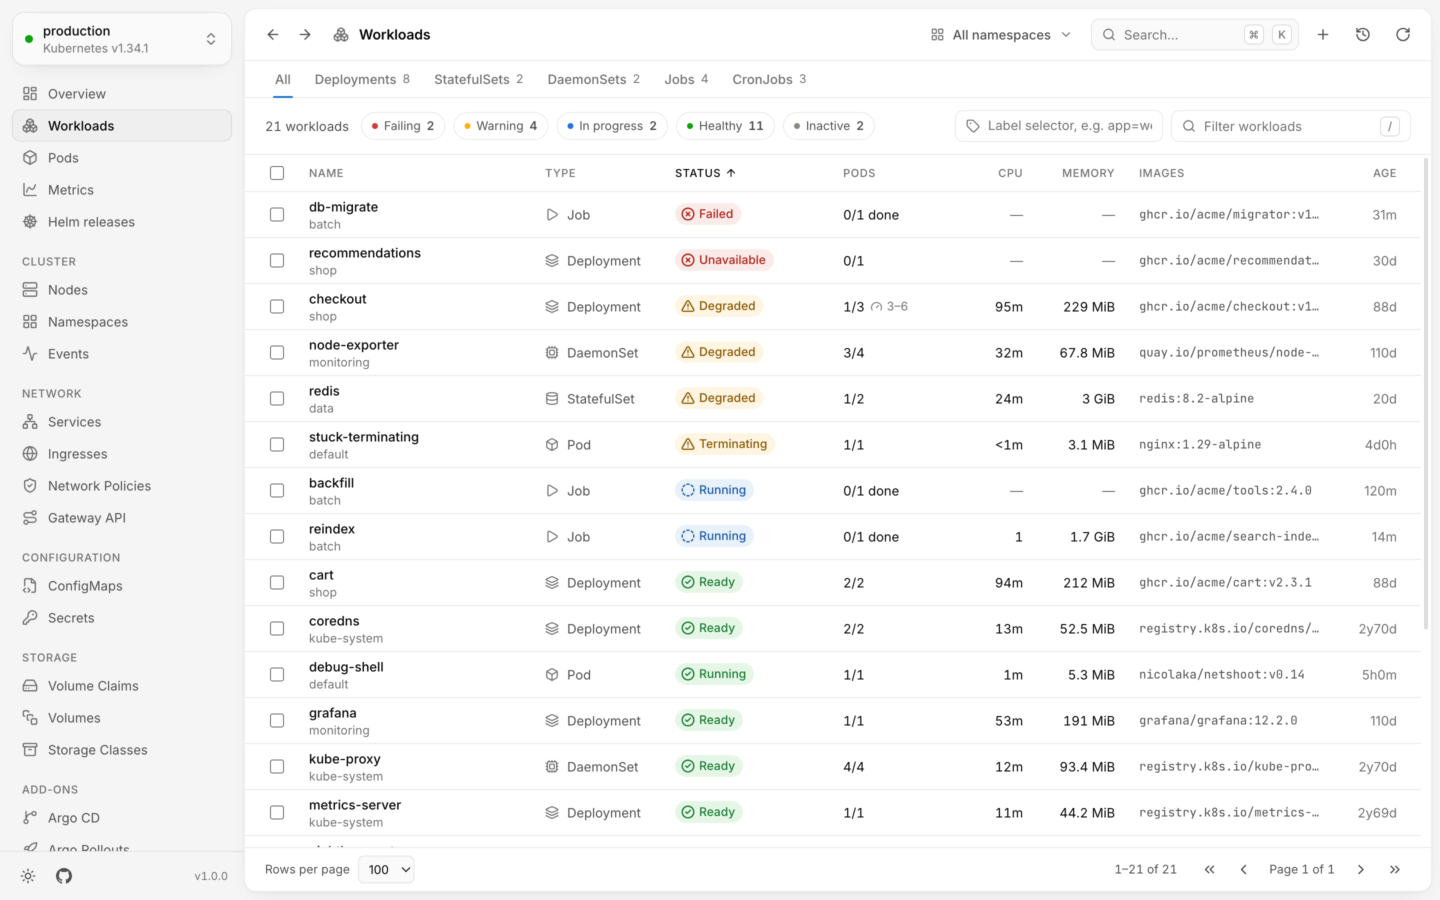
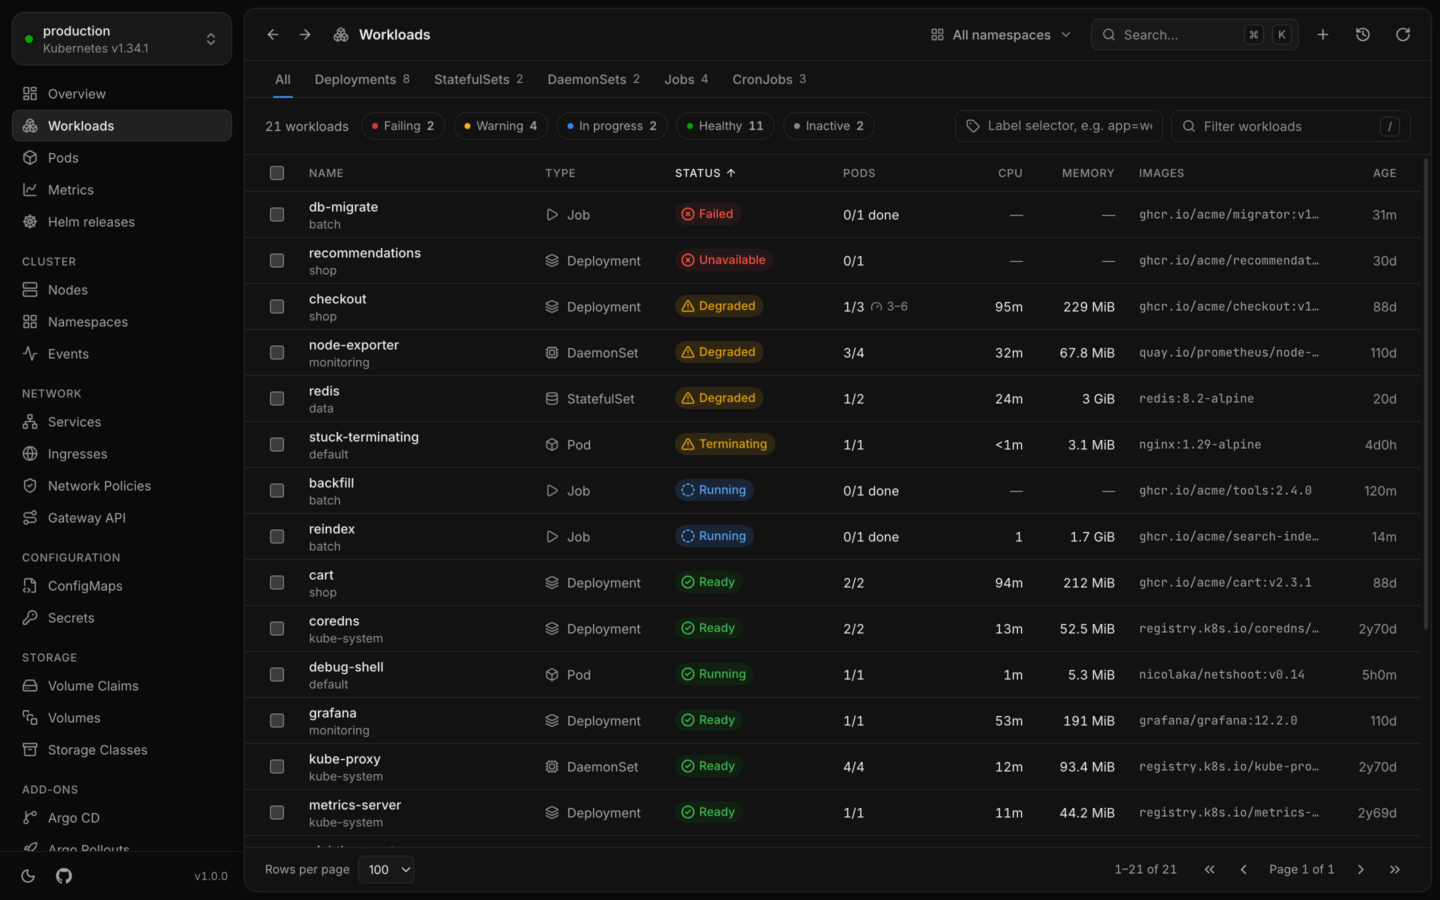 Statuses read the way you’d say them: Unavailable Degraded In progress Ready. The chips above the list keep only what’s Failing, Warning, In progress, Healthy or Inactive. How health works.
Look closer
Click a row, or move to it with ↓ and press ↵. Its details open next to the list, so you keep your place: the facts that matter for its kind, its pods and why they restart, its events, logs and YAML.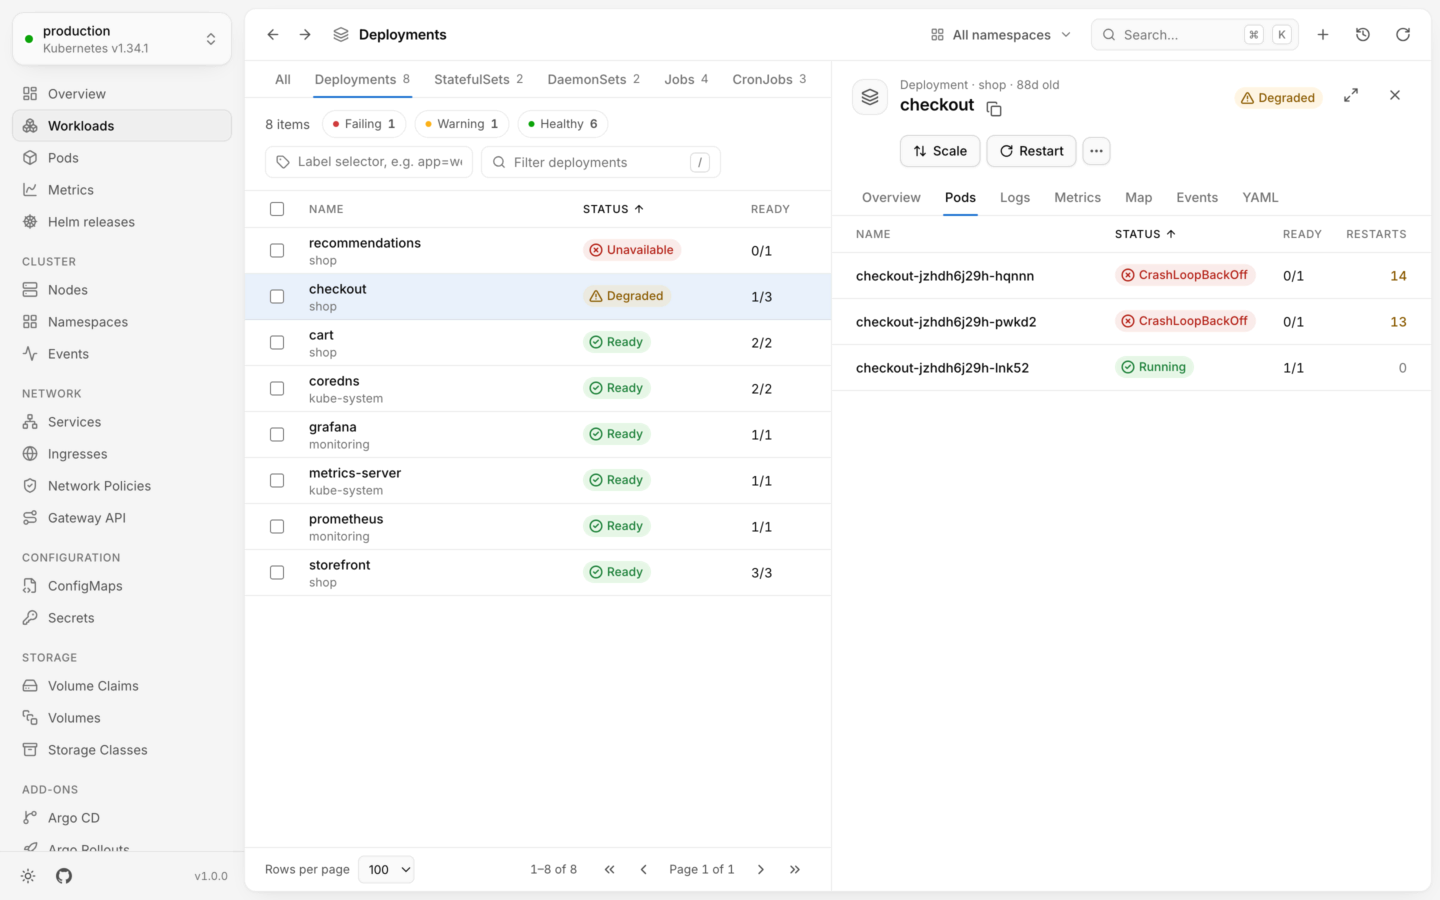
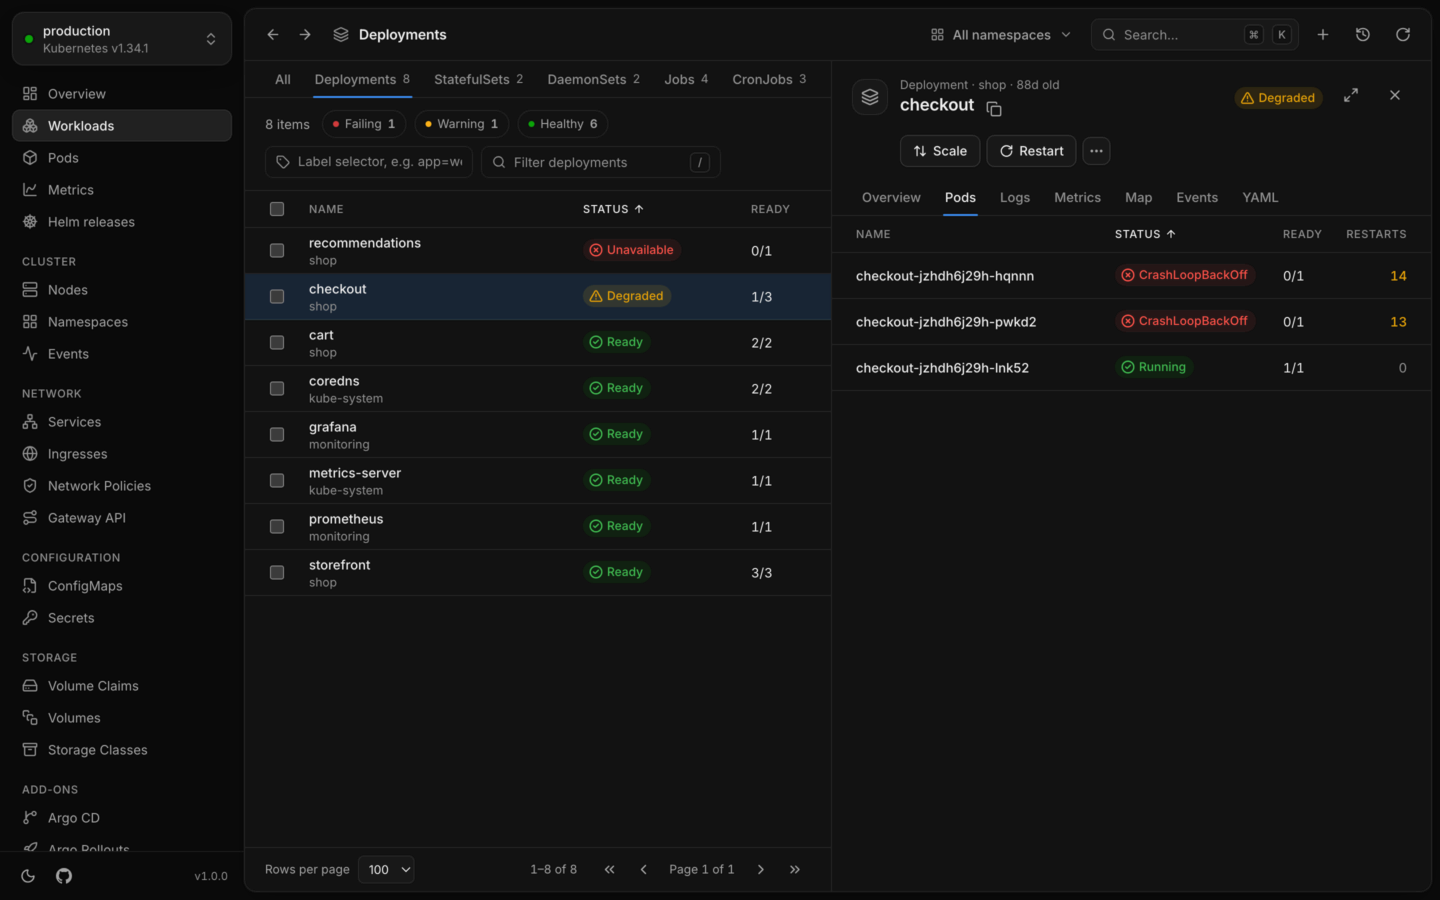 With the panel open, ↑ and ↓ open each row in turn, and Esc closes it. The detail panel.Its Map tab shows how it’s connected: what leads to it, like the gateway, ingress and services in front of it, and what it uses and runs on, down to the nodes. Whatever is missing or unwell along the way stands out.
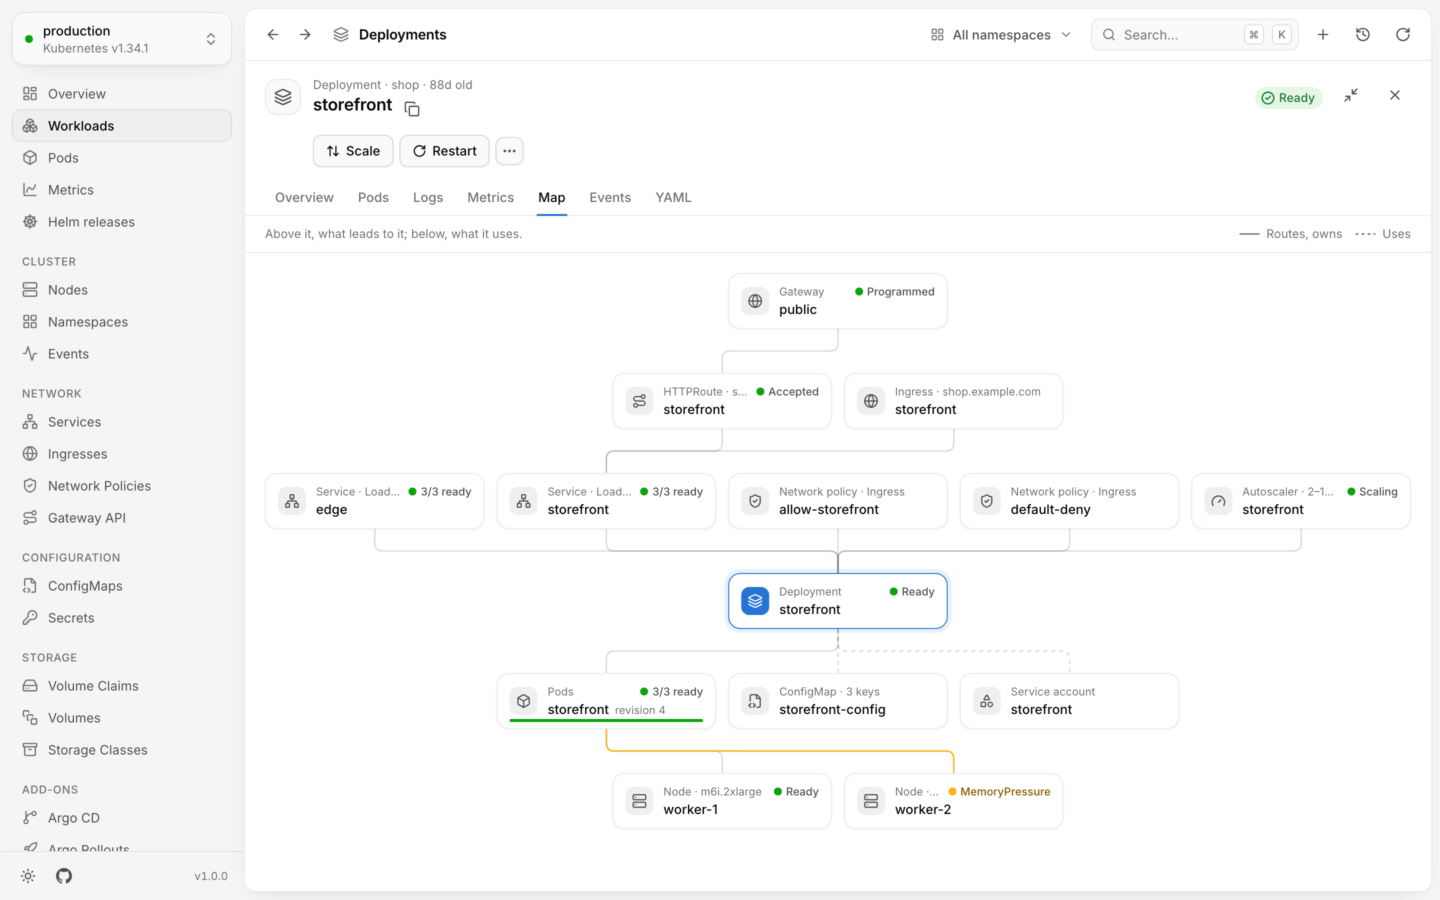
 The map.
Read the logs
The Logs tab of a workload merges every one of its pods, in the order lines were written, each marked with its pod. Pods that start later join in. Keep only errors or warnings, leave a pod out, or search.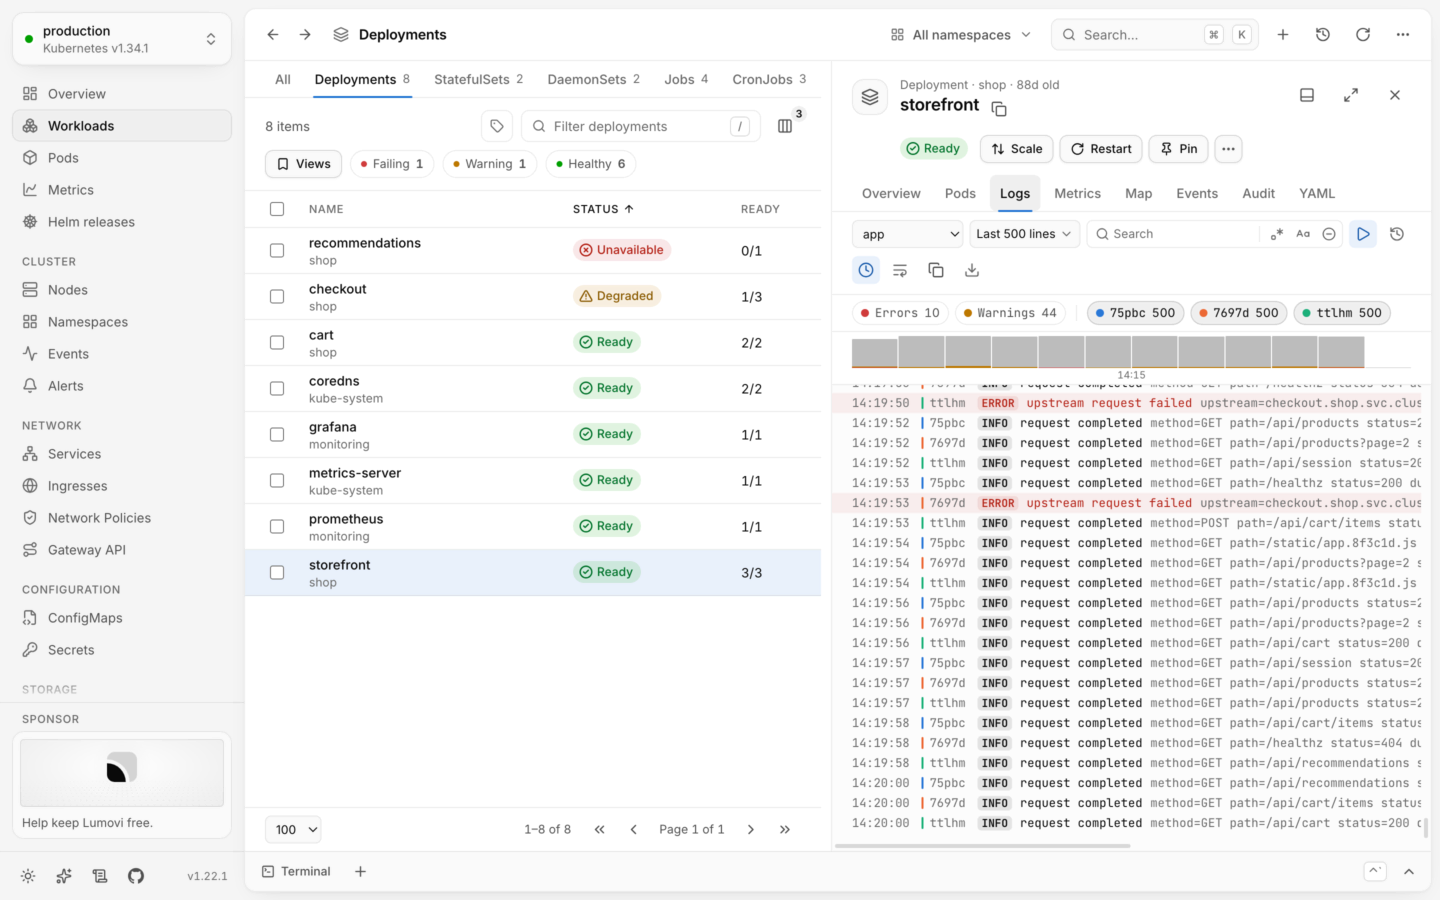
 A pod also has a Shell tab, for a terminal in its containers. Logs · Shells and debug containers.
Fix it, safely
The open object’s actions are right there: the common ones as buttons, the rest under ⋯ (or .). Every dialog names the cluster and shows the 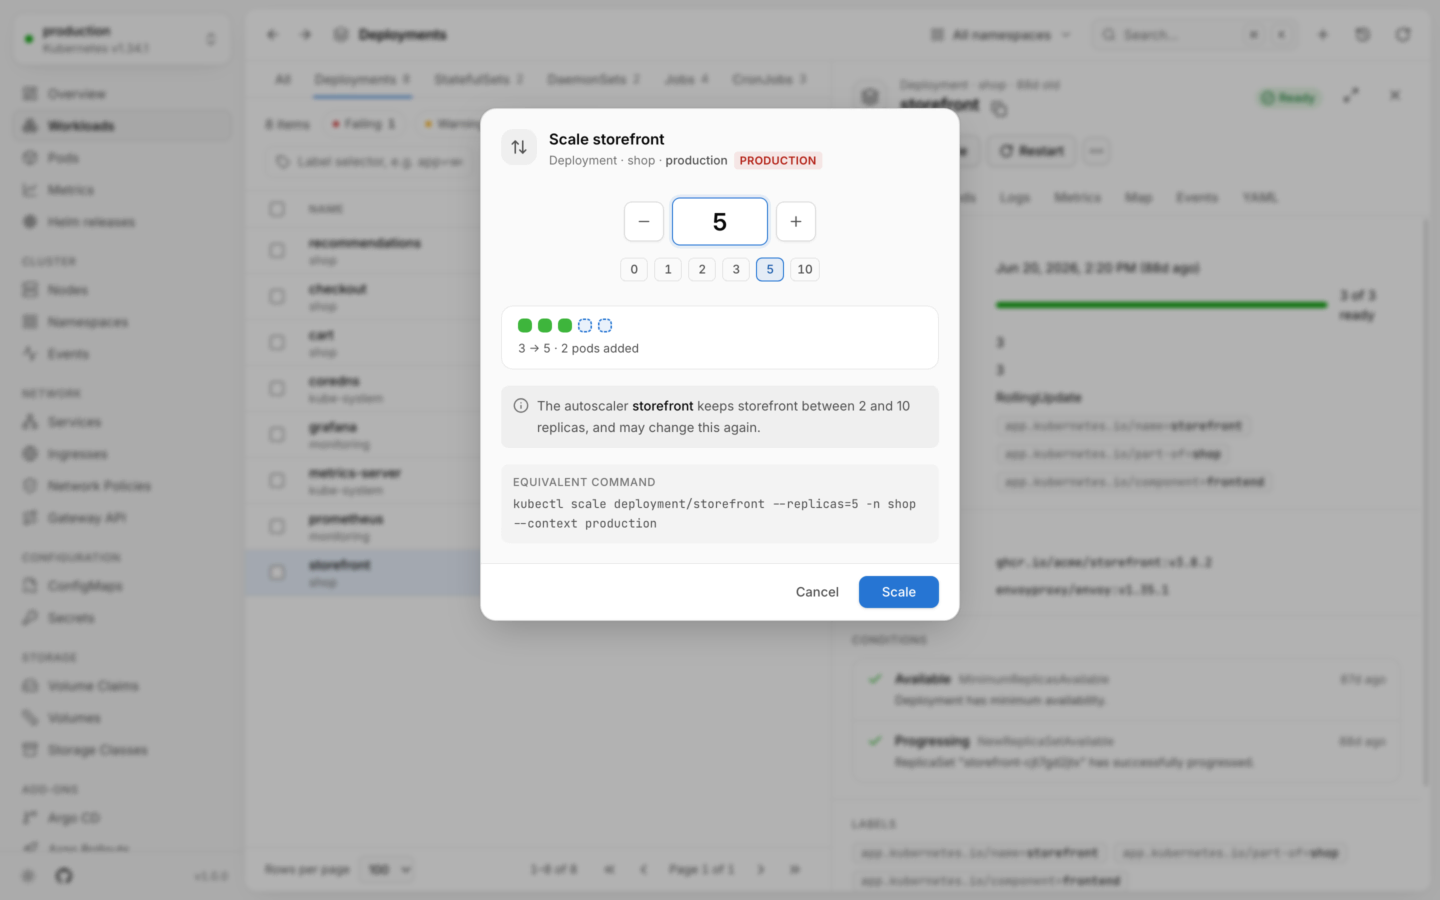
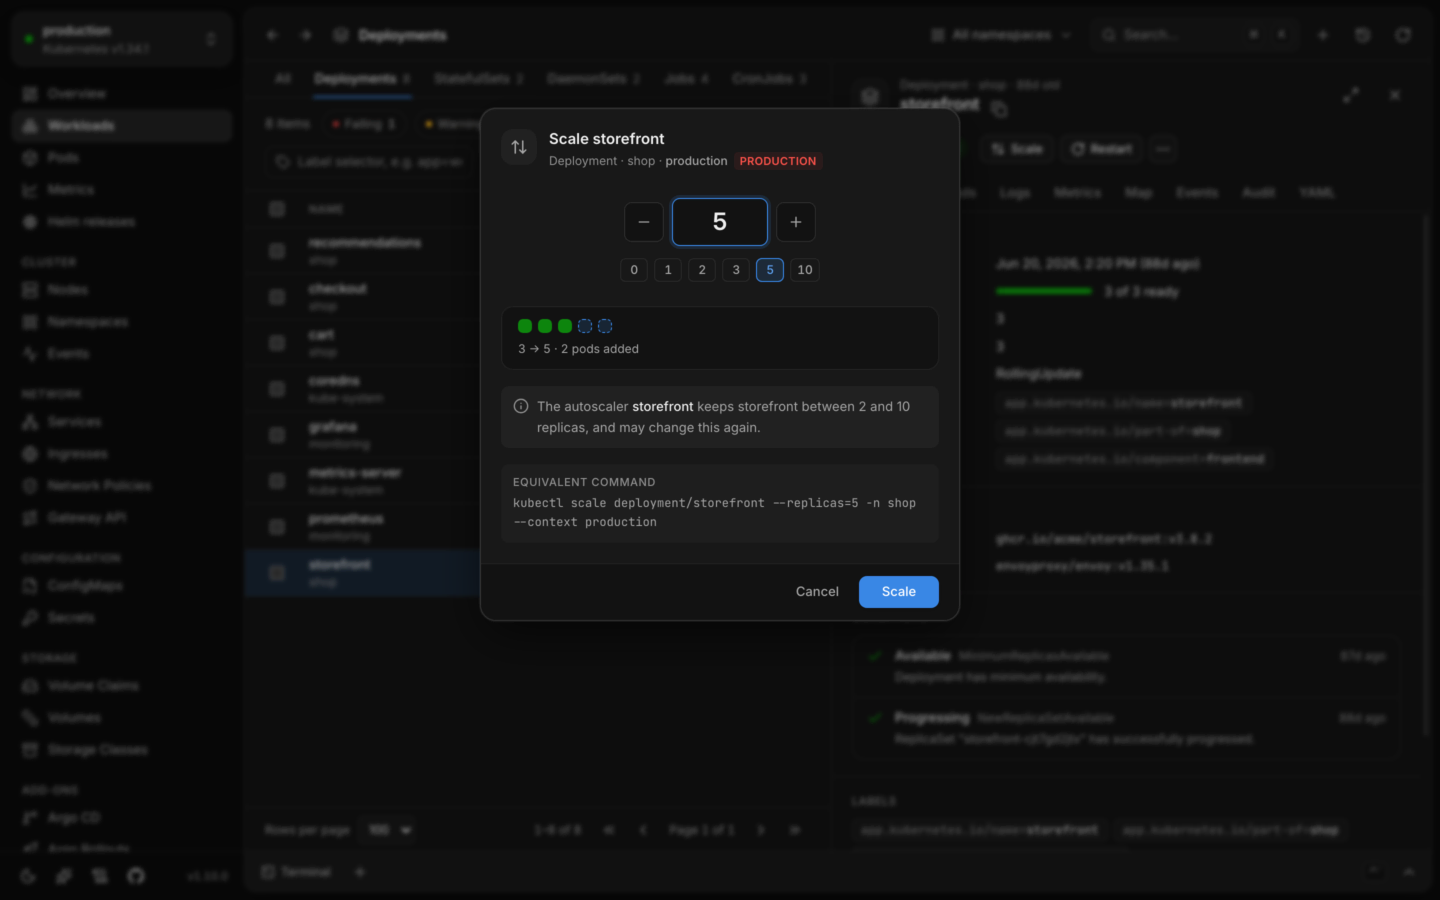 Once it’s done, the notification offers Undo for changes that can be taken back, like a scale. Changing things safely.
kubectl command it amounts to. Lumovi checks your permissions first, and disables what you can’t do, saying why.Go anywhere from the keyboard
Press ⌘K. Type a few letters to jump to any view, the page of a tool your cluster runs, any object already loaded, a namespace or another cluster, or to run an action on the object you have open.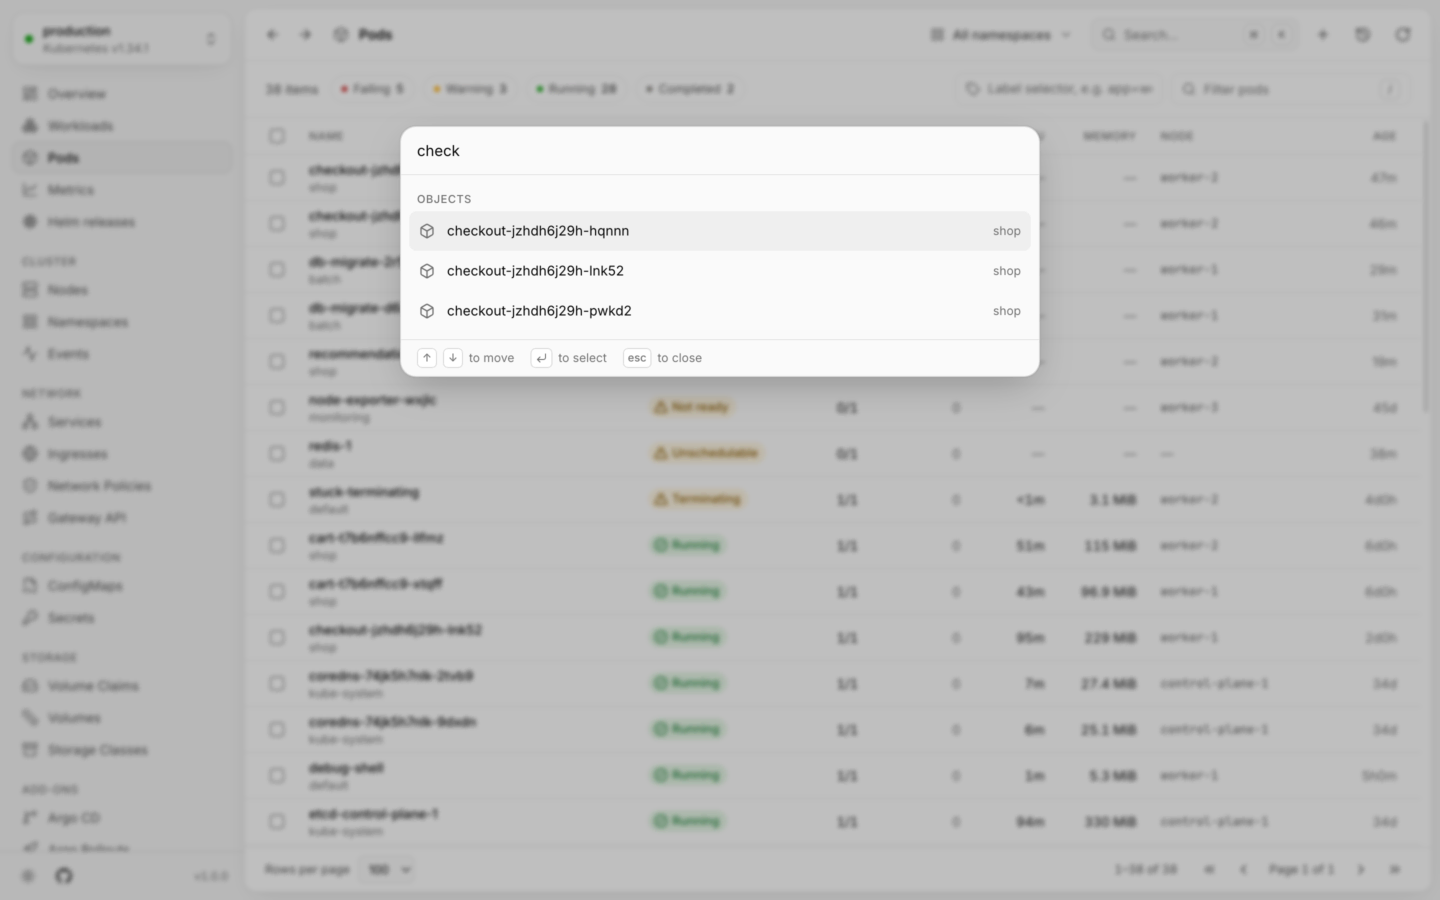
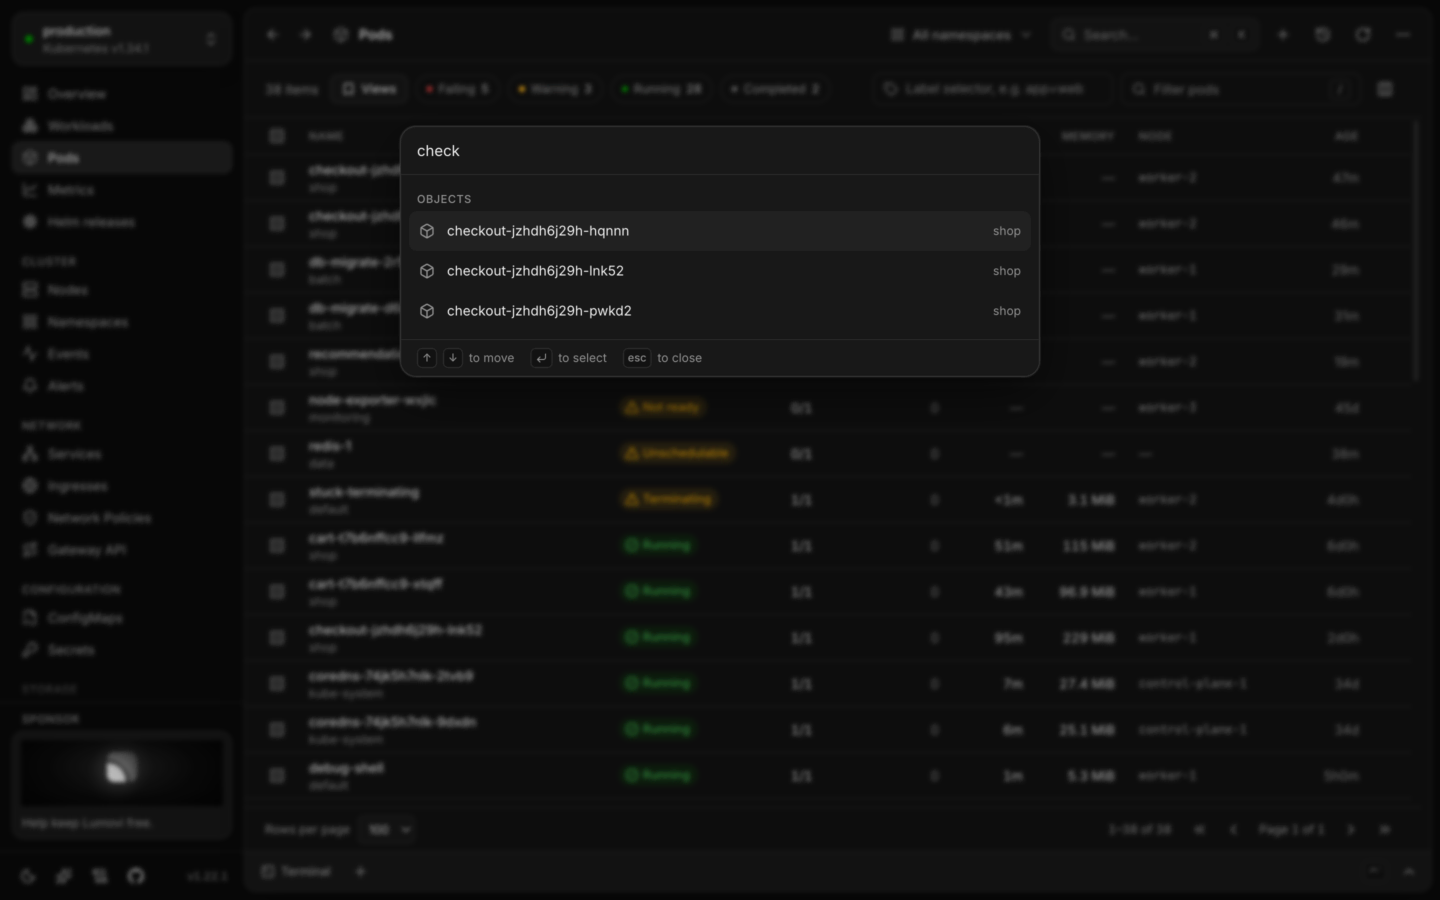 Most views also have a G shortcut, shown when you hover them in the sidebar, and ? lists them all. Keyboard shortcuts.
Where to next
Usage over time
Chart what namespaces, workloads and nodes use, from your Prometheus.
Right-sizing
What each workload should request, from a week of its usage.
The map
How an object is connected, from the gateway down to the nodes.
Helm releases
Every release, its values and revisions, and upgrades reviewed first.
Plugins
A page for each tool your cluster runs that Lumovi has a plugin for, like Argo CD, cert-manager or Karpenter.
Read-only mode
Look around a production cluster with changes turned off.